Yes. The interview combines coding, backend architecture, distributed systems, debugging, and behavioral discussions, making it one of the more comprehensive backend engineering interview processes.
Content
The OpenAI backend engineer interview is designed to evaluate much more than your ability to write efficient code. Backend engineers at OpenAI build and maintain systems that power products used by millions of developers and businesses around the world. These systems must handle enormous traffic, low-latency requirements, high availability, and rapid iteration while maintaining reliability and security.
As a result, the interview process focuses heavily on backend engineering fundamentals, distributed systems, infrastructure design, production debugging, and communication. While strong coding skills remain essential, interviewers also want to understand how you make engineering decisions, evaluate trade-offs, and design software that performs well in real production environments.
This guide covers everything you need to know about the OpenAI backend engineer interview, including the interview process, technical expectations, backend System Design, common interview questions, and an effective preparation roadmap.
The scale keeps climbing. Bloomberg reported on July 31, 2026, that OpenAI's models reach more than two million businesses alongside more than one billion active users. My view is that this is why backend interviewers care less about clever code and more about what happens when things break.
Why the OpenAI backend engineer interview is unique#
Just like the OpenAI software engineer interview, backend engineering at OpenAI involves solving complex infrastructure challenges instead of simply implementing business logic.
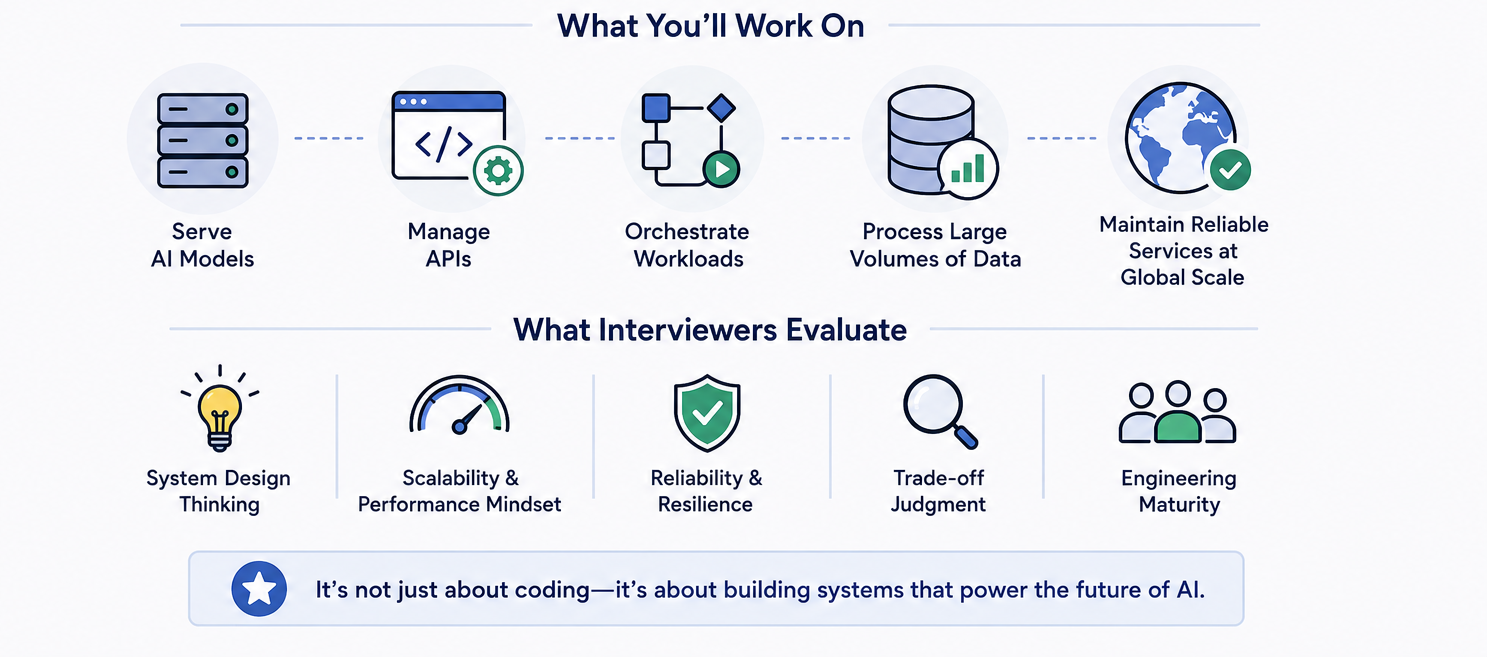
Engineers work on systems responsible for serving AI models, managing APIs, orchestrating workloads, processing large volumes of data, and maintaining reliable services at global scale. Because of this, interviewers look beyond coding ability to evaluate engineering maturity.
During the interview, you may be assessed on:
Backend architecture
API design
Distributed systems
Database design
Scalability
Reliability engineering
Performance optimization
Production debugging
Communication skills
Engineering trade-offs
Candidates who explain their decisions clearly often perform better than those who simply arrive at the correct answer.
What does the OpenAI backend engineer interview process look like?#
Although interview loops differ depending on the team, OpenAI's hiring process follows a fairly consistent structure.
Interview stage | What to expect |
Resume review | Experience with backend systems and production software |
Recruiter conversation | Career goals, technical background, motivation |
Technical coding interview | Live coding or practical backend problems |
Backend System Design | Architecture discussion focused on scalable systems |
Final interview loop | Multiple technical and behavioral interviews |
Hiring decision | Team matching and final review |
Backend candidates typically participate in several technical interviews covering coding, architecture, debugging, and engineering judgment.
Throughout the process, interviewers often encourage discussion rather than expecting perfect solutions immediately.
OpenAI's own interview guide confirms the shape. It says candidates "typically" go through "4–6 hours of final interviews with 4–6 people over 1–2 days," and that you "should expect to hear from us within one week" of the final round. On AI tools, it says expectations "vary by interview," so confirm the rules for each round with your recruiter.
In short, plan for a long final day and pace your energy. Our OpenAI interview process guide covers the company-wide loop in more detail.
Resume tips for backend engineering roles#
Your resume should demonstrate ownership of production systems rather than simply listing programming languages.
Strong backend resumes often highlight measurable engineering achievements.
Examples include:
Designed scalable APIs
Improved system reliability
Reduced infrastructure costs
Increased application performance
Built distributed services
Optimized database queries
Automated deployment pipelines
Led production incident resolution
Whenever possible, include metrics that demonstrate impact.
Instead of writing:
Improved application performance.
Write:
Reduced API latency by 45% across 20 million daily requests.
Quantifiable results immediately strengthen your application.
One warning from the interviewer's side of the table. In my experience, every number on a resume becomes a question, so be ready to explain how you measured that 45%, what the baseline was, and what you'd do differently.
Coding interview expectations#
OpenAI Coding interviews for the backend engineer role typically resemble real engineering work more than competitive programming contests.
Interviewers frequently evaluate:
Clean code
Maintainability
Edge-case handling
Testing strategy
Performance
Readability
Communication
Rather than rushing into implementation, successful candidates usually begin by clarifying requirements and discussing constraints.
Backend-focused coding topics often include:
Hash tables
Trees
Graphs
Queues
Priority queues
Concurrency
Thread safety
Caching
Rate limiting
API implementation
Production-quality thinking matters just as much as algorithmic efficiency.
Grokking the Coding Interview Patterns
Grokking the Coding Interview Patterns
I created Grokking the Coding Interview because I watched too many talented engineers fail interviews they should have passed. At Microsoft and Meta, I saw firsthand what separated the candidates who succeeded from the ones who didn't. It wasn't how many LeetCode problems they'd solved. It was whether they could look at an unfamiliar problem and know how to approach it the right way. That's what this course teaches. Rather than throwing hundreds of disconnected problems at you, we organize the entire coding interview around 28 fundamental patterns. Each pattern is a reusable strategy. Once you understand two pointers, for example, you can apply them to dozens of problems you've never seen before. The course walks you through each pattern step by step, starting with the intuition behind it, then building through increasingly complex applications. As with every course on Educative, you will practice in a hands-on way with 500+ challenges, 17 mock interviews, and detailed explanations for every solution. The course is available in Python, Java, JavaScript, Go, C++, and C#, so you can prep in the language you'll actually use in your interview. Whether you're preparing for your first FAANG loop or brushing up after a few years away from interviewing, this course will give you a repeatable framework for cracking the coding interview.
In my experience, backend candidates who ask "what happens if this is called twice?" before writing a line stand out in coding rounds. Idempotency and concurrency questions almost always arrive as follow-ups.
Two tools help you practice this. pytest makes edge-case tests cheap to write, and Hypothesis generates odd inputs you'd never think to try, like empty strings and huge integers.
Backend System Design is one of the most important interview rounds#
For backend engineering roles, System Design often carries significant weight.
Instead of designing consumer products alone, interviewers frequently explore backend infrastructure, microservices, distributed APIs, data pipelines, and service reliability.
Common backend design topics include:
URL shortener
Notification service
API gateway
Distributed cache
Message queue
Authentication service
Job scheduler
Logging platform
Metrics pipeline
Configuration service
During these discussions, interviewers usually introduce new constraints throughout the conversation.
For example:
Traffic suddenly increases by 10×
One database becomes unavailable
Latency requirements change
Global deployment is required
Storage costs increase dramatically
Strong candidates adapt their architecture while clearly explaining every trade-off.
Grokking Modern System Design Interview
Grokking Modern System Design Interview
For a decade, when developers talked about how to prepare for System Design Interviews, the answer was always Grokking Modern System Design Interview. This is that course — updated for the current tech landscape. As AI handles more of the routine work, engineers at every level are expected to operate with the architectural fluency that used to belong to Staff engineers. That's why System Design Interviews still determine starting level and compensation, and the bar keeps rising. I built this course from my experience building global-scale distributed systems at Microsoft and Meta — and from interviewing hundreds of candidates at both companies. The failure pattern I kept seeing wasn't a lack of technical knowledge. Even strong coders would hit a wall, because System Design Interviews don't test what you can build; they test whether you can reason through an ambiguous problem, communicate ideas clearly, and defend trade-offs in real time (all skills that matter more than ever now in the AI era). RESHADED is the framework I developed to fix that: a repeatable 45-minute roadmap through any open-ended System Design problem. The course covers the distributed systems fundamentals that appear in every interview – databases, caches, load balancers, CDNs, messaging queues, and more – then applies them across 13+ real-world case studies: YouTube, WhatsApp, Uber, Twitter, Google Maps, and modern systems like ChatGPT and AI/ML infrastructure. Then put your knowledge to the test with AI Mock Interviews designed to simulate the real interview experience. Hundreds of thousands of candidates have already used this course to land SWE, TPM, and EM roles at top companies. If you're serious about acing your next System Design Interview, this is the best place to start.
Rate limiting is a favorite, so here's the trade-off as I'd present it. The options are a fixed window counter, a sliding log, or a token bucket. My choice is a token bucket stored in Redis, because it allows short bursts while enforcing a steady average. The cost is a shared dependency on Redis and careful atomic updates, usually with a Lua script. I wouldn't use it for a single-instance internal service, where an in-memory limiter is plenty. What I'd do differently is return a Retry-After header from day one, since clients retry less aggressively when told when to come back.
A token bucket works like a coffee punch card that refills one stamp per minute. You can spend saved stamps in a burst, but never faster than they refill over time. For more prompts, see our complete System Design interview guide and the OpenAI System Design interview questions course.
Backend engineering concepts you should master#
Many candidates focus almost entirely on algorithms while underestimating backend engineering fundamentals.
A balanced preparation strategy should cover the following areas.
Backend topic | Importance |
REST APIs | Very High |
Distributed systems | Very High |
Databases | Very High |
SQL optimization | High |
NoSQL databases | High |
Caching | Very High |
Load balancing | Very High |
Message queues | High |
Event-driven architecture | High |
Authentication | High |
Observability | High |
Docker and containers | Medium |
Kubernetes | Medium |
CI/CD pipelines | Medium |
Understanding why a particular technology fits a specific problem is often more valuable than memorizing definitions.
Retries are the concept candidates most often get wrong. Marc Brooker of AWS warns in the Amazon Builders' Library that "when failures are caused by overload, retries that increase load can make matters significantly worse." His fix is jitter, which "adds some amount of randomness to the backoff to spread the retries around in time."
In short, mention backoff, jitter, and a retry budget whenever you add a retry to a design.
Expect production debugging discussions#
One area that distinguishes the OpenAI backend engineer interview from many traditional software engineering interviews is the emphasis on debugging production systems.
Interviewers may describe an issue such as:
API latency suddenly doubles.
Database connections are exhausted.
Requests begin timing out.
Memory usage continues increasing.
A service crashes intermittently.
Your goal is usually not to identify the answer immediately but to demonstrate a systematic debugging process.
A strong debugging approach often includes:
Gathering metrics
Reviewing logs
Isolating recent deployments
Reproducing the issue
Testing assumptions
Identifying bottlenecks
Proposing monitoring improvements
Interviewers appreciate structured thinking more than guesswork.
OpenAI's own December 2024 outage shows why this matters. A new telemetry service made every node in each cluster run expensive Kubernetes API operations, which overwhelmed the API servers that DNS-based service discovery depended on. The public write-up notes that "DNS caching made the issue far less visible until the rollouts had begun fleet-wide." The change had passed staging, because the problem only appeared in large clusters, and the overloaded control plane then locked engineers out of the fix.
The outage lasted about four hours and twenty minutes. The lesson for a junior engineer is that caches can hide failures, so watch control plane health during rollouts, not just CPU and memory.
For hands-on debugging steps, name real ones. py-spy dump shows what a stuck Python process is doing right now, and pg_stat_activity shows which Postgres queries are holding connections.
Behavioral interviews still matter#
Backend engineering is highly collaborative.
Engineers regularly work with infrastructure teams, AI researchers, product engineers, and security specialists.
Because of this, OpenAI includes behavioral interviews that explore collaboration, leadership, and communication.
Common questions include:
Tell me about a difficult production incident.
Describe your largest backend project.
Tell me about a disagreement with another engineer.
How do you balance speed and reliability?
What's the most challenging scalability issue you've solved?
Why do you want to work at OpenAI?
Good answers usually follow a clear structure:
Situation
Challenge
Actions
Technical decisions
Outcome
Lessons learned
Concrete examples are almost always stronger than hypothetical responses.
Grokking the Behavioral Interview
Grokking the Behavioral Interview
Behavioral interviews have become a decisive part of the hiring process across roles. Whether you’re a software engineer, product manager, or engineering leader, strong technical skills alone are no longer enough. Companies are evaluating how you think, communicate, and operate in real-world situations. That’s why preparing specifically for behavioral interviews is critical. This is why I built this course around a common gap: candidates often underestimate behavioral interviews or prepare for them too late. As a result, even strong candidates struggle to clearly articulate their experiences, decisions, and impact. The goal here is to give you a structured way to approach behavioral questions with clarity and confidence. You’ll learn how to break down common behavioral interview questions, structure your answers, and communicate your experiences effectively. The course also includes a video recording feature, allowing you to practice your responses, review them, and improve over time. By the end, you’ll have a repeatable approach to behavioral interviews, one that helps you present your experiences clearly and perform with confidence in any interview setting.
In my experience, the strongest incident stories include what you changed afterward, such as a new alert, a runbook, or a deploy guard. Interviewers want to know the system got safer, not just that you survived the night.
Common backend interview questions#
Although every interview is different, many backend concepts appear repeatedly.
Examples include:
How would you design a scalable API?
How would you implement rate limiting?
Explain optimistic versus pessimistic locking.
How would you scale a notification system?
Design a distributed cache.
How would you reduce API latency?
Explain eventual consistency.
How would you monitor backend services?
Design an authentication system.
How would you migrate a database without downtime?
Practicing these questions helps build confidence during technical discussions.
For the zero-downtime migration question, name the expand-and-contract pattern. Add the new column as nullable, backfill it, switch reads and writes, then enforce the constraint last. We hit the reason for this ordering in our own testing below.
Where this broke for us
These four problems came up while we tested this guide's snippets on Python 3.13, SQLAlchemy 2.1.5, and SQLite 3.45.
Problem 1. Latency that scaled with traffic. Ten concurrent requests took 1.00 second instead of 0.10. The root cause was a blocking time.sleep inside an async handler, which froze the event loop for everyone. Timing ten calls with and without the blocking call isolated it. Replacing it with asyncio.sleep restored 0.10 seconds, and in production you'd move blocking work to a thread pool.
Problem 2. Exhausted connections. We saw "QueuePool limit of size 2 overflow 1 reached, connection timed out, timeout 1.00." The root cause was connections opened without being closed. Shrinking the pool to two made the leak appear on the fourth request instead of hours later. Opening connections in a with block fixed it, and ten sequential requests succeeded.
Problem 3. A migration that couldn't run. Adding a required column failed with "Cannot add a NOT NULL column with default value NULL." The root cause was enforcing the constraint before existing rows had a value. Adding the column as nullable and backfilling first worked.
Problem 4. A rate limiter that doubled its limit. A fixed window of 100 per minute allowed 200 requests within about one second around the window boundary. A sliding log allowed exactly 100.
In short, every one of these maps to a production debugging prompt from the list above.
How to prepare for the OpenAI backend engineer interview#
A structured study plan generally produces better results than randomly solving interview questions.
Weeks 1–2#
Strengthen your programming fundamentals.
Focus on:
Data structures
Algorithms
Backend coding exercises
Clean code practices
Weeks 3–4#
Study backend architecture.
Cover topics such as:
Distributed systems
REST APIs
Databases
Caching
Networking
Weeks 5–6#
Practice interview simulations.
Include:
Backend System Design
Production debugging
Behavioral interviews
Communication exercises
Final week#
Review your previous engineering projects.
You should be prepared to explain:
Architecture decisions
Performance optimizations
Technical trade-offs
Lessons learned
Challenges encountered
Your own projects frequently become discussion topics during interviews.
Mistakes candidates commonly make#
Even experienced backend engineers sometimes struggle because they overlook important aspects of the interview.
Some common mistakes include:
Jumping into implementation too quickly
Ignoring scalability
Not discussing trade-offs
Weak communication
Forgetting monitoring and observability
Neglecting security considerations
Designing overly complex systems
Failing to consider failure scenarios
Interviewers generally value thoughtful engineering judgment over unnecessarily complicated architectures.
Failure scenarios include your own config changes. In November 2025, a database permissions change at Cloudflare made a query return extra rows, which doubled the size of a bot management feature file and caused its proxy software to fail, as The Register reported. CEO Matthew Prince said, "An outage like today is unacceptable." The lesson for juniors is to validate generated config files as strictly as user input, because bad data spreads as fast as bad code.
Final thoughts#
The OpenAI backend engineer interview is designed to identify engineers who can build reliable, scalable, and maintainable backend systems. Success requires far more than solving coding challenges quickly. You need to demonstrate strong engineering judgment, communicate technical ideas clearly, and understand how large-scale distributed systems behave under real production conditions.
The best preparation strategy combines coding practice with backend architecture, distributed systems, debugging experience, and mock interviews. By focusing on practical engineering skills rather than memorizing interview questions, you'll be much better prepared for the kinds of conversations OpenAI engineers have every day.
Frequently Asked Questions
Is the OpenAI backend engineer interview difficult?
Is the OpenAI backend engineer interview difficult?
Does OpenAI ask backend System Design questions?
Does OpenAI ask backend System Design questions?
Are LeetCode problems enough to prepare for the OpenAI backend interview?
Are LeetCode problems enough to prepare for the OpenAI backend interview?
What programming languages can I use in the OpenAI backend engineer interview?
What programming languages can I use in the OpenAI backend engineer interview?
How long should I prepare for the OpenAI backend engineer interview?
How long should I prepare for the OpenAI backend engineer interview?
Written By:
Naeem ul Haq
Free Resources