Building software at an AI company involves engineering challenges that look very different from those found in many conventional applications. If you are preparing for a Mistral AI Software Engineer interview, you should be ready to demonstrate strong programming fundamentals while showing that you can reason about performance, scalability, distributed systems, and the infrastructure surrounding modern AI models.
This guide explains what to prepare for the Mistral AI Software Engineer interview, including coding, System Design, distributed systems, AI infrastructure, behavioral questions, and role-specific technical topics. You will also find a structured preparation roadmap that can help you turn a broad collection of subjects into a manageable interview strategy.
What is the Mistral AI Software Engineer interview?#
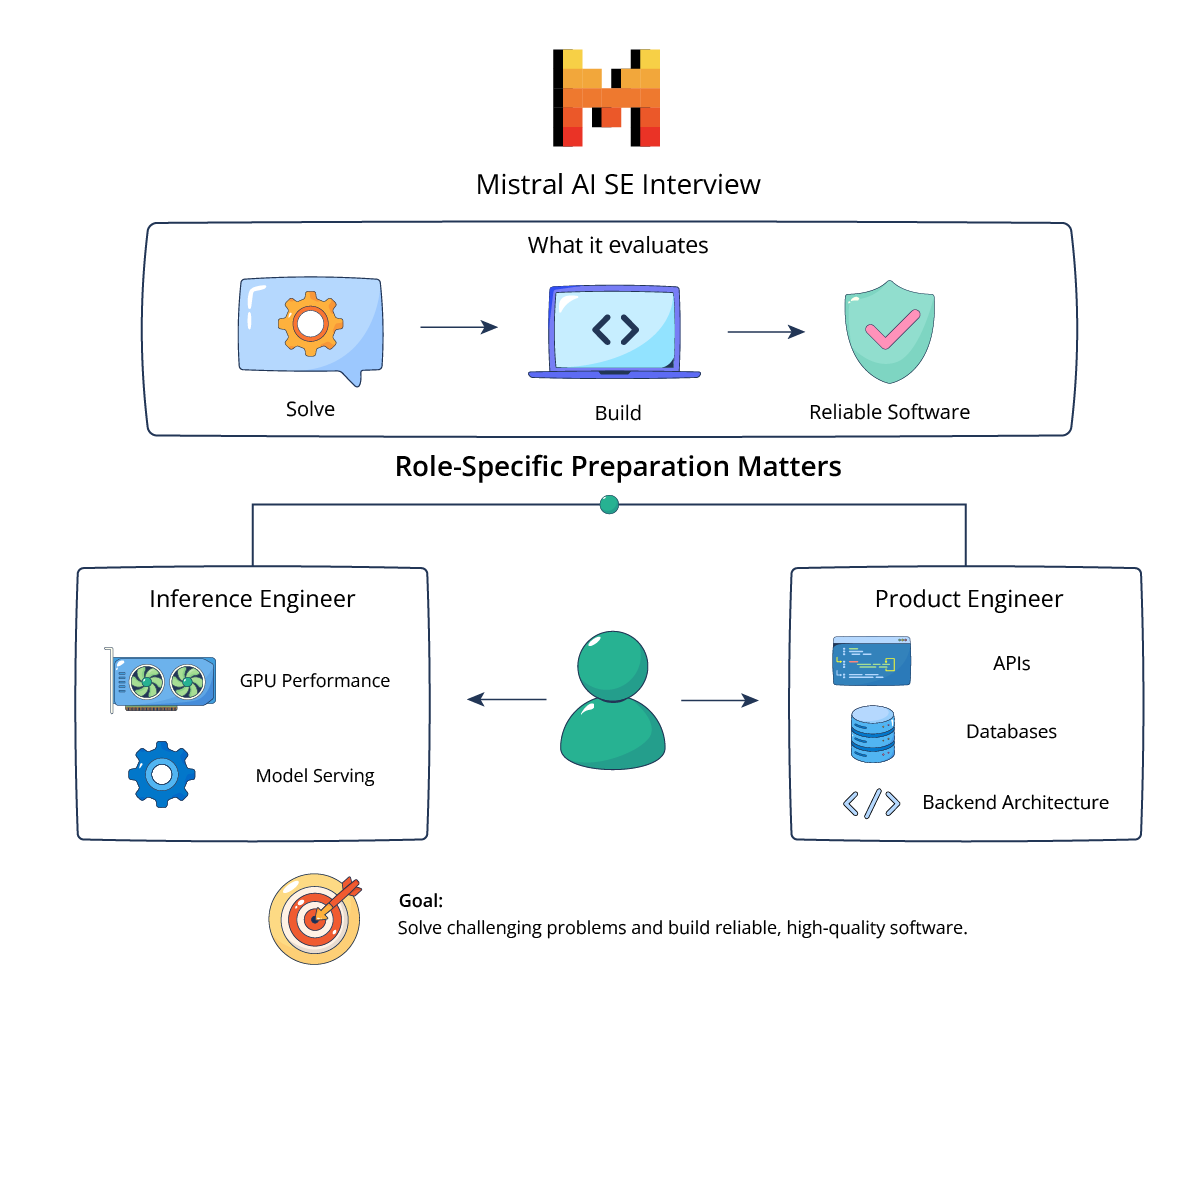
The Mistral AI Software Engineer interview evaluates whether you can solve technically challenging problems and turn those solutions into reliable software. Depending on the team, that can mean building high-performance inference systems, developing APIs and products around AI models, improving distributed infrastructure, or creating tools that allow other engineers and researchers to work efficiently.
That breadth makes role-specific preparation especially important because two candidates interviewing for software engineering positions can face very different technical expectations. An inference engineer may need deeper knowledge of GPU performance and model serving, while a product-oriented engineer could spend considerably more time discussing APIs, backend architecture, databases, and customer-facing systems.
A useful way to organize your preparation is around the competencies the interview may evaluate rather than assuming every candidate encounters an identical sequence.
Interview area | What you should prepare to demonstrate |
Initial conversations | Experience, motivation, technical background, and role alignment |
Coding and problem solving | Algorithms, data structures, correctness, efficiency, and implementation |
Software engineering | Code quality, testing, debugging, APIs, and maintainability |
System Design | Scalability, distributed architecture, reliability, storage, and trade-offs |
Role-specific depth | AI infrastructure, inference, backend, systems, platform, or product engineering |
Behavioral discussions | Ownership, collaboration, ambiguity, execution, and learning |
Use your recruiter and the position description as the primary sources for determining the actual interview format. Once you understand the role's technical emphasis, you can adjust your preparation instead of spreading your time equally across every possible AI engineering topic.
What skills should you prepare for the Mistral AI Software Engineer interview?#
Strong software engineering fundamentals should form the foundation of your preparation because AI infrastructure still depends on reliable software. You should be comfortable taking an unfamiliar technical problem, clarifying its requirements, developing a solution, implementing it cleanly, and discussing how its performance changes under different constraints.
At the same time, Mistral AI operates in a domain where efficiency can matter at several layers of the stack. Depending on your target role, understanding distributed computing, concurrency, networking, accelerators, model inference, and production reliability can help you handle deeper technical follow-ups.
Data structures and algorithms#
Algorithms remain an effective way for interviewers to evaluate structured problem-solving because they reveal how you reason under constraints. You should be comfortable with arrays, strings, hash maps, trees, graphs, heaps, queues, stacks, recursion, searching, sorting, and dynamic programming.
Focus on recognizing patterns rather than memorizing completed solutions. If you can identify when a problem calls for graph traversal, binary search, a heap, a sliding window, or dynamic programming, you will be much better prepared when an interviewer changes the constraints of a familiar problem.
Learn Data Structures and Algorithms

Modern applications, including search engines and AI systems, rely on efficient data handling and fast decision-making. As software systems scale, the difference between functional code and performant code becomes critical. Proficiency in data structures and algorithms is essential; it underpins the design of reliable, scalable, and high-performance systems. I built this course from my background in computer science research and my work in intelligent systems, where efficiency and optimization directly impact real-world outcomes. My experience with adaptive AI, neural networks, and intelligent tutoring systems shows a consistent pattern: developers often struggle more with selecting efficient problem-solving approaches than with syntax. This course focuses on addressing that gap. You will learn Data Structures and Algorithms in Python through a structured, hands-on approach that prioritizes clarity and practical application. Instead of memorizing concepts, you will understand how to apply arrays, linked lists, trees, graphs, and algorithms like recursion, sorting, and graph traversal to real problems. You will also build intuition for time and space complexity using Big-O analysis. Thousands of learners use Educative to strengthen their problem-solving skills and prepare for technical interviews. If you want to write efficient code, think like an engineer, and confidently solve complex problems in Python, this course is the right place to start.
Programming fundamentals#
Your interview language should be one in which you can write correct, readable code while explaining your decisions simultaneously. Python is especially relevant throughout the AI ecosystem, while C++ can become important for performance-sensitive infrastructure and systems work, although the appropriate language ultimately depends on the role.
Review memory management, concurrency, asynchronous programming, error handling, testing, object-oriented design, and language-specific performance considerations where they are relevant. Interviewers may use a relatively simple coding task as a starting point before asking how your implementation behaves under concurrency, larger inputs, or production workloads.
Writing production-quality code#
An interview solution does not need the architecture of a production service, but your code should still demonstrate engineering discipline. Clear naming, small logical units, sensible abstractions, explicit error handling, and appropriate testing can distinguish an engineer from someone who has prepared exclusively through competitive programming.
When you finish an implementation, consider what could fail outside the happy path. Explaining validation, observability, testing, and failure handling demonstrates that you think beyond getting the expected output for one example.
Grokking the Coding Interview Patterns
I created Grokking the Coding Interview because I watched too many talented engineers fail interviews they should have passed. At Microsoft and Meta, I saw firsthand what separated the candidates who succeeded from the ones who didn't. It wasn't how many LeetCode problems they'd solved. It was whether they could look at an unfamiliar problem and know how to approach it the right way. That's what this course teaches. Rather than throwing hundreds of disconnected problems at you, we organize the entire coding interview around 28 fundamental patterns. Each pattern is a reusable strategy. Once you understand two pointers, for example, you can apply them to dozens of problems you've never seen before. The course walks you through each pattern step by step, starting with the intuition behind it, then building through increasingly complex applications. As with every course on Educative, you will practice in a hands-on way with 500+ challenges, 17 mock interviews, and detailed explanations for every solution. The course is available in Python, Java, JavaScript, Go, C++, and C#, so you can prep in the language you'll actually use in your interview. Whether you're preparing for your first FAANG loop or brushing up after a few years away from interviewing, this course will give you a repeatable framework for cracking the coding interview.
System Design for Mistral AI software engineering roles#
System Design preparation is particularly useful for experienced candidates because production AI systems introduce demanding requirements around throughput, latency, availability, and computational resources. Your interviewer may be interested in how you design general distributed services or may introduce requirements involving model inference and AI workloads.
Begin every design by establishing functional requirements, scale, latency expectations, availability requirements, and important constraints. Once these are clear, you can choose services, databases, queues, caches, storage systems, and communication patterns that solve specific problems rather than adding technologies simply because they appear in common System Design diagrams.
Grokking Modern System Design Interview
For a decade, when developers talked about how to prepare for System Design Interviews, the answer was always Grokking System Design. This is that course — updated for the current tech landscape. As AI handles more of the routine work, engineers at every level are expected to operate with the architectural fluency that used to belong to Staff engineers. That's why System Design Interviews still determine starting level and compensation, and the bar keeps rising. I built this course from my experience building global-scale distributed systems at Microsoft and Meta — and from interviewing hundreds of candidates at both companies. The failure pattern I kept seeing wasn't a lack of technical knowledge. Even strong coders would hit a wall, because System Design Interviews don't test what you can build; they test whether you can reason through an ambiguous problem, communicate ideas clearly, and defend trade-offs in real time (all skills that matter more than ever now in the AI era). RESHADED is the framework I developed to fix that: a repeatable 45-minute roadmap through any open-ended System Design problem. The course covers the distributed systems fundamentals that appear in every interview – databases, caches, load balancers, CDNs, messaging queues, and more – then applies them across 13+ real-world case studies: YouTube, WhatsApp, Uber, Twitter, Google Maps, and modern systems like ChatGPT and AI/ML infrastructure. Then put your knowledge to the test with AI Mock Interviews designed to simulate the real interview experience. Hundreds of thousands of candidates have already used this course to land SWE, TPM, and EM roles at top companies. If you're serious about acing your next System Design Interview, this is the best place to start.
Example System Design prompt: Design an LLM inference API#
Imagine you are asked to design an API that allows developers to send prompts to a large language model and receive generated responses. The system needs authentication, usage tracking, streaming output, rate limiting, low latency, high availability, and the ability to handle large variations in request volume.
Your design could include an API gateway, authentication service, request scheduler, inference workers, accelerator-aware resource management, streaming infrastructure, usage metering, caching where appropriate, and observability. As the discussion develops, you should be ready to explain how the system handles overloaded workers, long prompts, failed inference requests, traffic spikes, and expensive model replicas.
The interesting part of this question is not naming components because most candidates can draw several boxes connected by arrows. The deeper challenge is explaining how requests move through the system, where bottlenecks emerge, and which trade-offs you would make between latency, throughput, reliability, and infrastructure cost.
Design and Build Great Web APIs
At the start of this course, you’ll be introduced to a handful of important practices and principles for designing and building APIs that are robust, reliable, and resilient. You’ll also acquire skills in a wide range of developer tools, including tools for design, documentation, building, testing, security, and deployment. You'll learn the best practices for modeling an APIs lifecycle using Donald Norman’s action lifecycle. Then, you’ll learn how to use the sequence diagram for designing APIs and describing them using ALPS. For sketching an API, you will learn about Gehry's sketches. You will also cover OpenAPI and SwaggerHub for API mocking. Moreover, the usage of DARRT and NodeJS will be covered for building APIs. You'll finish with learning how to use the Postman for testing APIs and then deploy them using Heroku. By the end of this course, you will have an in-depth understanding of how to make fully functional efficient APIs from its inception to its deployment.
Distributed systems concepts worth studying#
Distributed systems become particularly relevant when software coordinates expensive computing resources or serves models across many machines. You should understand replication, partitioning, consistency, fault tolerance, leader election, load balancing, queues, retries, idempotency, backpressure, and distributed observability.
Do not study these concepts only as definitions because interviewers can make them practical very quickly. For example, you might need to explain what happens when an inference worker disappears midway through a request or how your system prevents aggressive retries from making an overloaded service even less stable.
Reliability and failure recovery#
Large systems fail in ways that cannot be prevented completely, which makes graceful recovery an essential engineering capability. Practice reasoning about timeouts, retries, exponential backoff, circuit breakers, health checks, replication, checkpointing, and degraded service modes.
A useful interview habit is to ask yourself what happens when every major component becomes unavailable. You do not need to eliminate every possible failure, but you should understand which failures are tolerable, how they are detected, and how the system recovers.
Distributed Systems for Practitioners
This course is about establishing the basic principles of distributed systems. It explains the scope of their functionality by discussing what they can and cannot achieve. It also covers the basic algorithms and protocols of distributed systems through easy-to-follow examples and diagrams that illustrate the thinking behind some design decisions and expand on how they can be practiced. This course also discusses some of the issues that might arise when doing so, eliminates confusion around some terms (e.g., consistency), and fosters thinking about trade-offs when designing distributed systems. Moreover, it provides plenty of additional resources for those who want to invest more time in gaining a deeper understanding of the theoretical aspects of distributed systems.
How much machine learning should you know?#
The depth of machine learning knowledge needed for a Mistral AI Software Engineer interview depends strongly on the position. A software engineer working on inference infrastructure may need substantial understanding of model execution and accelerators, while a product or backend engineer may need enough ML knowledge to build reliable services around models without being expected to conduct ML research.
At a minimum, understanding the vocabulary of modern LLM systems can make your preparation more complete. Training, inference, transformers, tokens, context windows, embeddings, attention, quantization, batching, fine-tuning, and model serving are useful concepts to understand from an engineering perspective.
You should also understand why these concepts matter operationally. Longer contexts can increase computational requirements, batching can improve throughput while affecting latency, and quantization can reduce resource requirements while introducing quality and implementation trade-offs.
Grokking the Machine Learning Interview
Machine learning interviews at top tech companies now focus more on open-ended system design problems. “Design a recommendation system.” “Design a search ranking system.” “Design an ad prediction pipeline.” These questions evaluate your ability to reason about machine learning systems end-to-end. However, most candidates prepare for isolated concepts instead of system-level design. This course focuses specifically on building that System Design muscle. You’ll work through 9 real-world ML System Design problems (the same questions asked at Meta, Google, Amazon, and Microsoft) and learn a repeatable methodology for breaking each one down: defining the problem, choosing metrics, selecting model architectures, designing data pipelines, and evaluating trade-offs. Each system you design builds on practical ML techniques covered earlier in the course: embeddings, transfer learning, online experimentation, model debugging, and performance considerations. By the time you’re designing your third or fourth system, you'll have the technical vocabulary and judgment to explain why your design choices work. This is exactly what interviewers are looking for. The course also includes 6 mock interviews so you can practice articulating your designs under realistic conditions. If you have an ML or System Design interview coming up at any major tech company, this course will help you walk in with a clear framework for tackling whatever they throw at you.
AI inference and model serving#
Inference is where trained models are used to generate outputs for real requests, which creates a distinct set of engineering problems. Serving an LLM efficiently requires balancing response latency, throughput, memory utilization, request scheduling, model size, and available accelerator resources.
Depending on the role, you may benefit from understanding continuous batching, KV caching, quantization, model parallelism, tensor parallelism, streaming generation, and accelerator utilization. You do not need identical depth in every concept, but you should be able to connect relevant optimizations to measurable system behavior.
Example inference question#
Suppose users complain that an LLM application's responses become dramatically slower during peak traffic. An interviewer might ask how you would investigate the problem before changing the architecture.
A strong approach begins with measurement by examining queue time, time to first token, inter-token latency, GPU or accelerator utilization, memory pressure, request sizes, batch behavior, and error rates. From there, you can determine whether the bottleneck comes from scheduling, model execution, networking, capacity, or another layer before proposing an optimization.
Coding questions you should practice#
The coding portion of your Mistral AI Software Engineer interview preparation should emphasize correctness, reasoning, and efficiency. Practice under realistic time constraints while explaining your approach aloud because communication becomes harder when you are simultaneously solving an unfamiliar problem.
Organizing questions by patterns can make your practice considerably more effective.
Problem category | Concepts worth practicing |
Arrays and strings | Two pointers, sliding windows, prefix sums |
Hash maps and sets | Counting, grouping, caching, fast lookup |
Trees | DFS, BFS, recursion, traversal, tree properties |
Graphs | Connectivity, shortest paths, topological sorting |
Heaps | Priority queues, Top-K, scheduling |
Dynamic programming | State transitions, memoization, tabulation |
Search | Binary search, boundaries, search on answer |
Concurrency-oriented problems | Synchronization, shared state, race conditions |
For every problem, practice explaining a straightforward approach before introducing an optimization. This creates a clear reasoning trail and gives you something correct to build upon instead of becoming stuck while searching for the theoretically best solution immediately.
How to communicate during technical interviews#
Technical communication can substantially affect interview performance because your interviewer cannot evaluate reasoning that remains entirely inside your head. Explain assumptions, identify constraints, describe your approach before coding, and mention meaningful trade-offs while you work.
Avoid narrating every keystroke because useful communication focuses on decisions rather than syntax. The interviewer needs to understand why you chose a data structure, how you know the algorithm is correct, and what you would change if the constraints became significantly larger.
Handle hints collaboratively#
Receiving a hint does not mean you have failed the interview because technical discussions are often intentionally interactive. Listen carefully, incorporate the new information, and explain how it changes your reasoning instead of defending an approach that no longer fits.
This response demonstrates adaptability, which matters in engineering environments where new evidence frequently changes technical decisions. Being able to update your thinking is considerably more useful than insisting that your first idea must be correct.
Backend and API engineering#
For backend-oriented positions, expect discussions around API design, databases, authentication, rate limiting, asynchronous processing, caching, and service reliability. AI APIs introduce additional challenges because requests can be expensive, responses can stream for extended periods, and computational requirements can vary dramatically between requests.
You should be comfortable designing APIs that remain understandable while supporting versioning, quotas, usage metering, retries, and clear error semantics. Consider how clients should respond to partial failures and how your backend prevents one expensive workload from degrading the experience for everyone else.
Performance optimization#
Performance is particularly important when software interacts with computationally expensive AI models. A seemingly small improvement in resource utilization can have significant effects when repeated across large numbers of inference requests.
Interviewers may therefore explore profiling, memory usage, CPU and GPU utilization, caching, batching, network overhead, serialization, concurrency, and algorithmic complexity. Develop the habit of measuring first because optimizing the wrong layer can make a system more complicated without addressing its actual bottleneck.
Behavioral preparation for Mistral AI#
Behavioral discussions provide an opportunity to demonstrate how you operate when engineering problems involve ambiguity, pressure, and collaboration. Prepare examples involving difficult debugging situations, technical disagreements, production incidents, ambitious projects, changing requirements, and situations where you had to acquire unfamiliar knowledge quickly.
Interviewers can only grade reasoning they hear, so narrate decisions, not keystrokes. Say why you chose a heap, how you know the loop terminates, and what changes at 100x scale.
Your answers should establish enough context for the interviewer to understand the problem while keeping your individual contribution clear. Explain the decisions you made, why you made them, what happened afterward, and what you would change if you encountered the same situation again.
For behavioral rounds, reported culture conversations cover autonomy, leading teams, and working across time zones. Prepare stories on debugging under pressure, disagreements, incidents, and learning fast, each with what you decided, why, and what you’d change. Ownership stories land best when the problem was ambiguous and nobody assigned it to you. Keep your individual contribution clear without pretending a team project was a solo act.
Prepare for questions about ownership#
Smaller and rapidly evolving technology organizations can require engineers to operate across traditional boundaries, which makes ownership an important theme to prepare for. Think about projects where you identified a problem independently, drove a solution, coordinated with other people, and remained responsible after the initial implementation.
The strongest examples usually involve some uncertainty rather than perfectly defined tasks. Demonstrating that you can turn ambiguous goals into executable engineering work can be particularly useful when discussing environments where products and technical capabilities evolve quickly.
Why do you want to work at Mistral AI?#
Your answer should go beyond saying that generative AI is exciting because that statement could apply to almost any company working with language models. Research Mistral AI's products, technical direction, engineering challenges, and the particular team you are interviewing with so that your motivation connects to actual work.
You can then connect those interests to your experience with distributed systems, developer tools, backend engineering, performance optimization, AI infrastructure, or another relevant area. A compelling answer explains what technical problems interest you, why this environment is a strong place to work on them, and what your existing experience allows you to contribute.
A five-week Mistral AI Software Engineer interview preparation plan#
A structured plan helps you maintain balance between coding practice and the deeper systems knowledge that AI engineering positions can require. Adjust the schedule based on the job description because an infrastructure candidate and a product engineer should not allocate their preparation time identically.
Week | Primary focus | Preparation goal |
Week 1 | Algorithms and programming fundamentals | Refresh core patterns and identify weak areas |
Week 2 | Advanced coding, concurrency, and code quality | Improve implementation and debugging skills |
Week 3 | System Design and distributed systems | Practice architecture and failure scenarios |
Week 4 | AI infrastructure and role-specific knowledge | Build depth relevant to the target position |
Week 5 | Mock interviews and behavioral preparation | Improve communication under interview conditions |
During the first two weeks, practice fewer problems at greater depth rather than maximizing your daily problem count. Revisit difficult problems several days later and solve them without referring to your previous implementation so you can distinguish genuine understanding from short-term recognition.
During weeks three and four, practice System Design aloud and deliberately introduce failures into your architecture. Ask what happens when traffic triples, an inference worker fails, storage becomes slow, the queue grows uncontrollably, or a dependency becomes unavailable.
Common mistakes candidates make#
Preparation can become overwhelming because an AI software engineering position appears to require knowledge of everything from algorithms to GPU architecture. Avoiding a few common mistakes can keep your preparation focused on skills that are actually likely to improve your performance.
Spending all your time studying machine learning#
Mistral AI builds AI technology, but a Software Engineer interview still requires excellent software engineering fundamentals. Unless your specific position demands deep ML expertise, do not sacrifice coding, systems, debugging, and architecture preparation simply to learn increasingly advanced model theory.
Use the job description to decide how deeply you need to study machine learning. Your goal is to understand the technical domain well enough to solve the engineering problems associated with your role.
Memorizing System Design diagrams#
Memorized architectures break down quickly when an interviewer changes one requirement. Practice deriving designs from requirements so that each database, queue, cache, service, and communication mechanism has a reason to exist.
When discussing your architecture, explain what you deliberately chose not to add as well. Knowing when a system does not need additional complexity is an important part of engineering judgment.
Optimizing before measuring#
Performance-sensitive environments can tempt candidates to immediately propose caches, parallelism, batching, or specialized infrastructure. A stronger engineering response begins by determining what is actually slow and collecting enough evidence to identify the bottleneck.
This principle applies equally to debugging questions and System Design. Establish observable symptoms, identify relevant metrics, form hypotheses, and then make changes that address measurable problems.
Neglecting behavioral preparation#
Technical candidates frequently leave behavioral preparation until the night before the interview because they assume experience will make the answers obvious. Under interview pressure, however, even strong experiences can become confusing stories when you have not decided which details actually demonstrate your contribution.
Prepare several flexible stories and practice telling them naturally. Focus on ownership, technical judgment, collaboration, failures, learning, and measurable impact rather than memorizing a separate answer for every possible question.
What to do during the final week#
Your final week should emphasize consolidation, realistic practice, and recovery rather than adding entire new areas to your study plan. Review your strongest coding patterns, revisit difficult System Design problems, refresh relevant AI infrastructure concepts, and practice behavioral responses aloud.
Reread the job description and identify every technical requirement you would struggle to discuss confidently for five minutes. Those gaps deserve more attention than another random set of algorithm questions because the position itself remains the clearest indicator of what knowledge is relevant.
Final thoughts#
Preparing for the Mistral AI Software Engineer interview requires strong software engineering fundamentals combined with an understanding of the technical challenges surrounding modern AI systems. Coding, System Design, distributed computing, reliability, performance, and communication should form the foundation of your preparation, while your specific role determines how deeply you need to study inference, accelerators, or machine learning infrastructure.
The goal should not be memorizing every question that could possibly appear because no preparation plan can guarantee that. Develop the ability to reason from requirements, implement clean solutions, diagnose unfamiliar problems, discuss architectural trade-offs, and adapt when new information appears, and you will be preparing for skills that remain valuable regardless of the exact interview format.
Free Resources